AI defence work
Vigil
Perception software. It watches live video, decides what is happening, grades how serious it is, and keeps the clip that proves it. It does not identify anybody, and that is deliberate.
AI defence work
Perception software. It watches live video, decides what is happening, grades how serious it is, and keeps the clip that proves it. It does not identify anybody, and that is deliberate.
Vigil · the wall
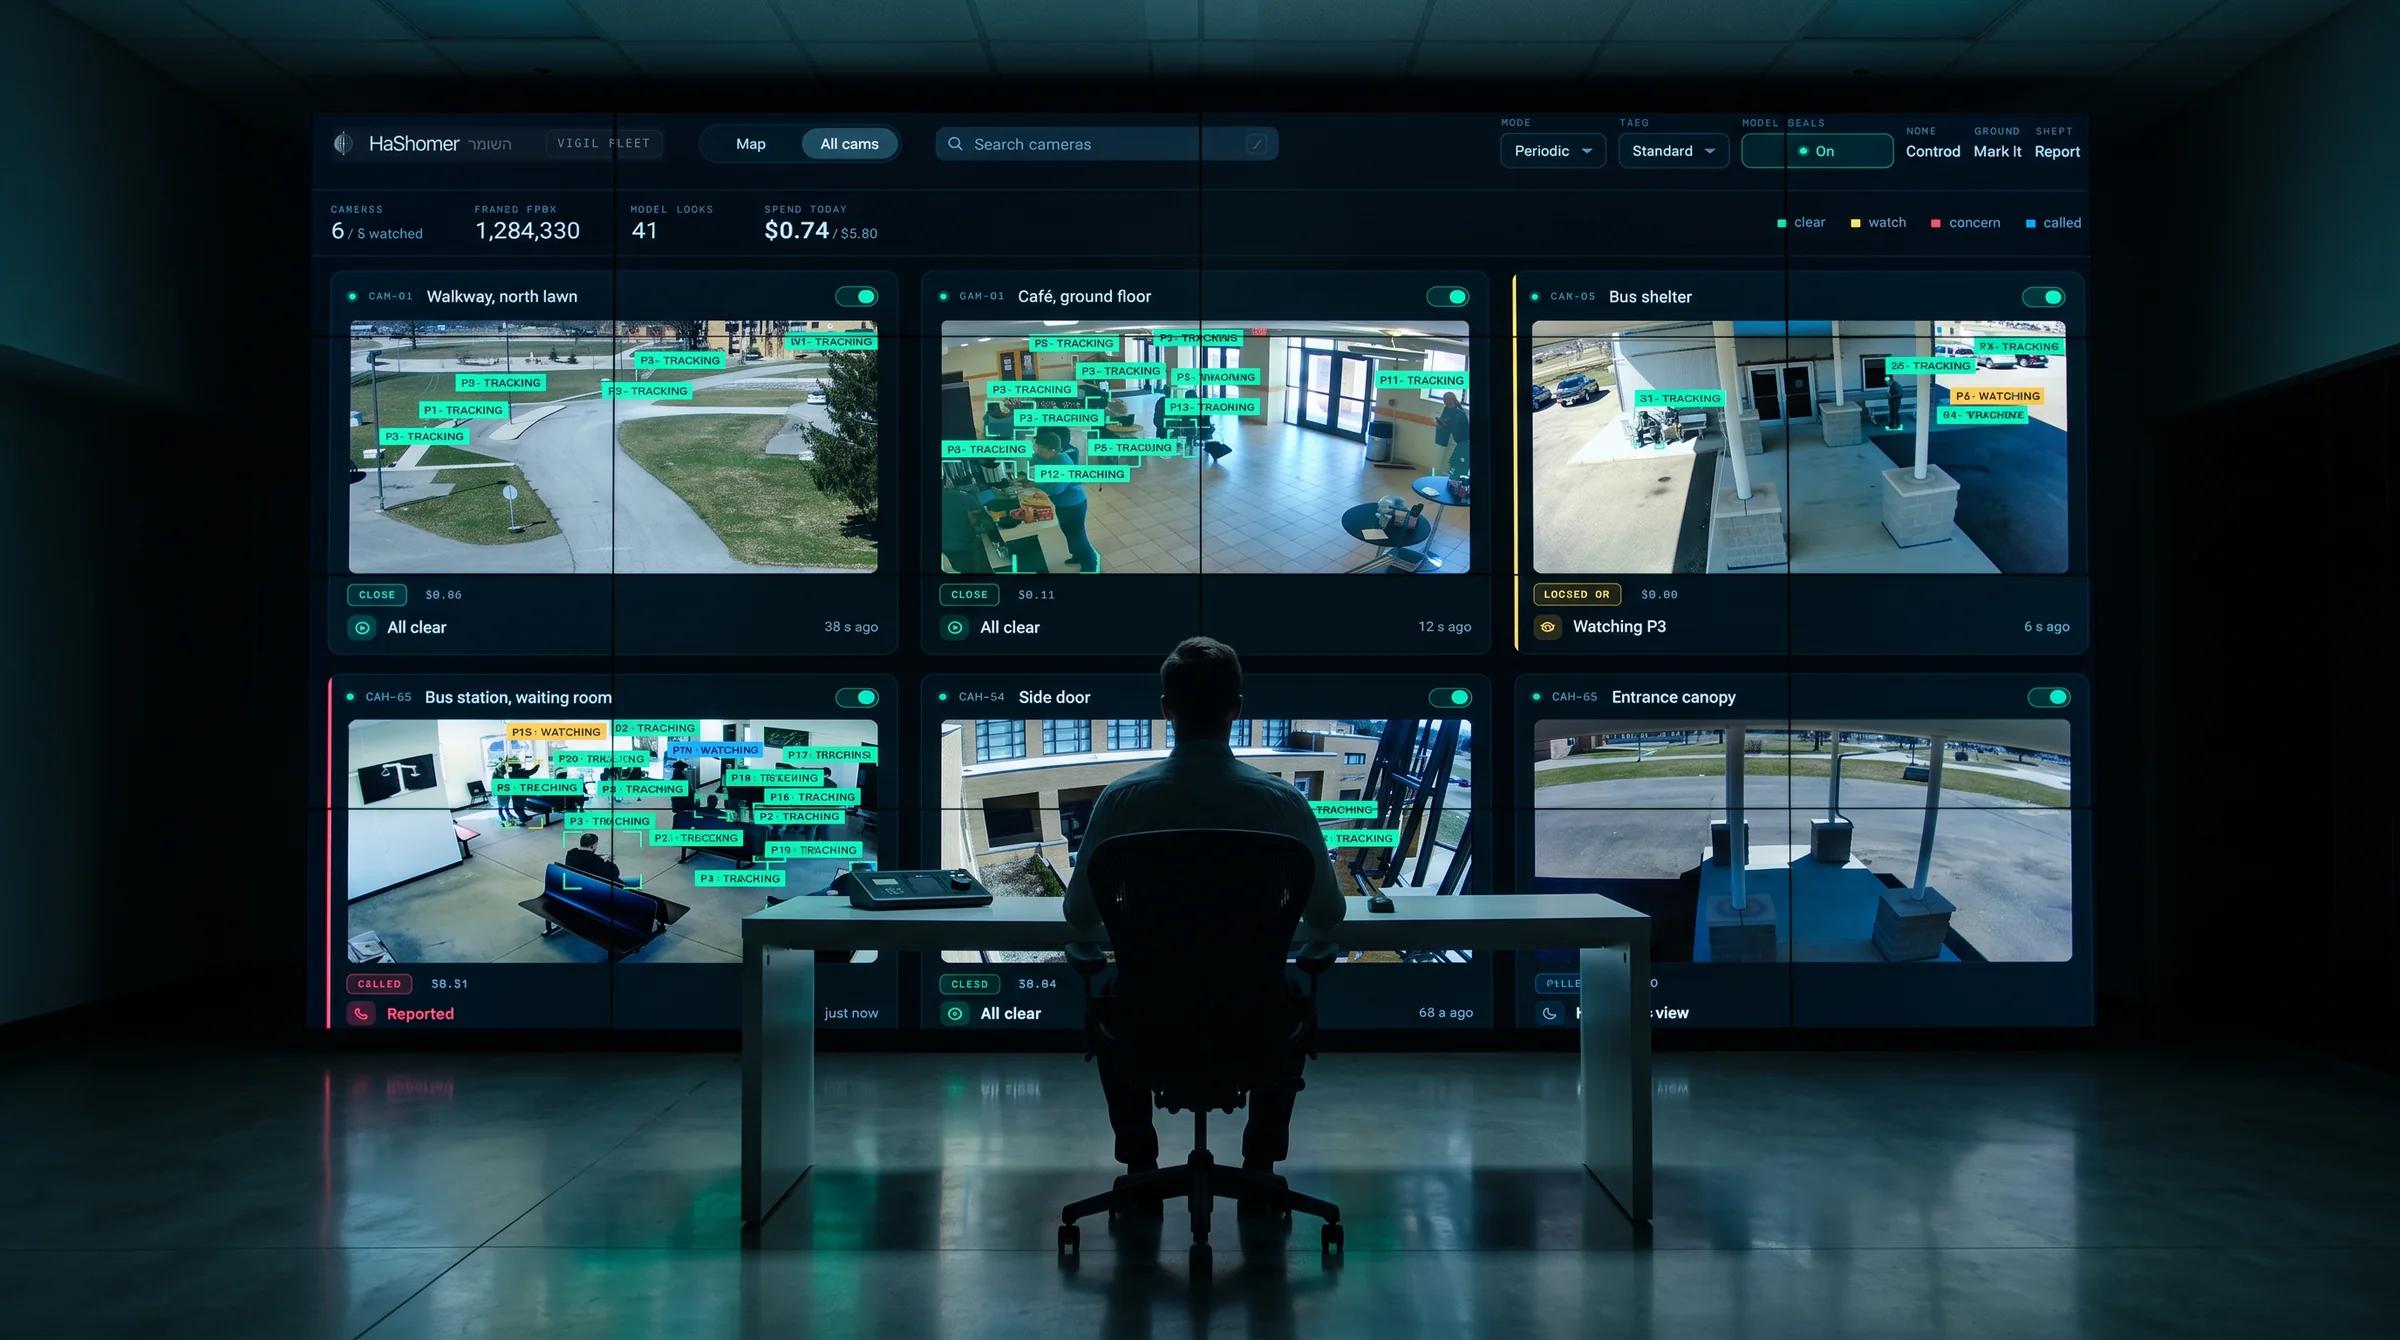
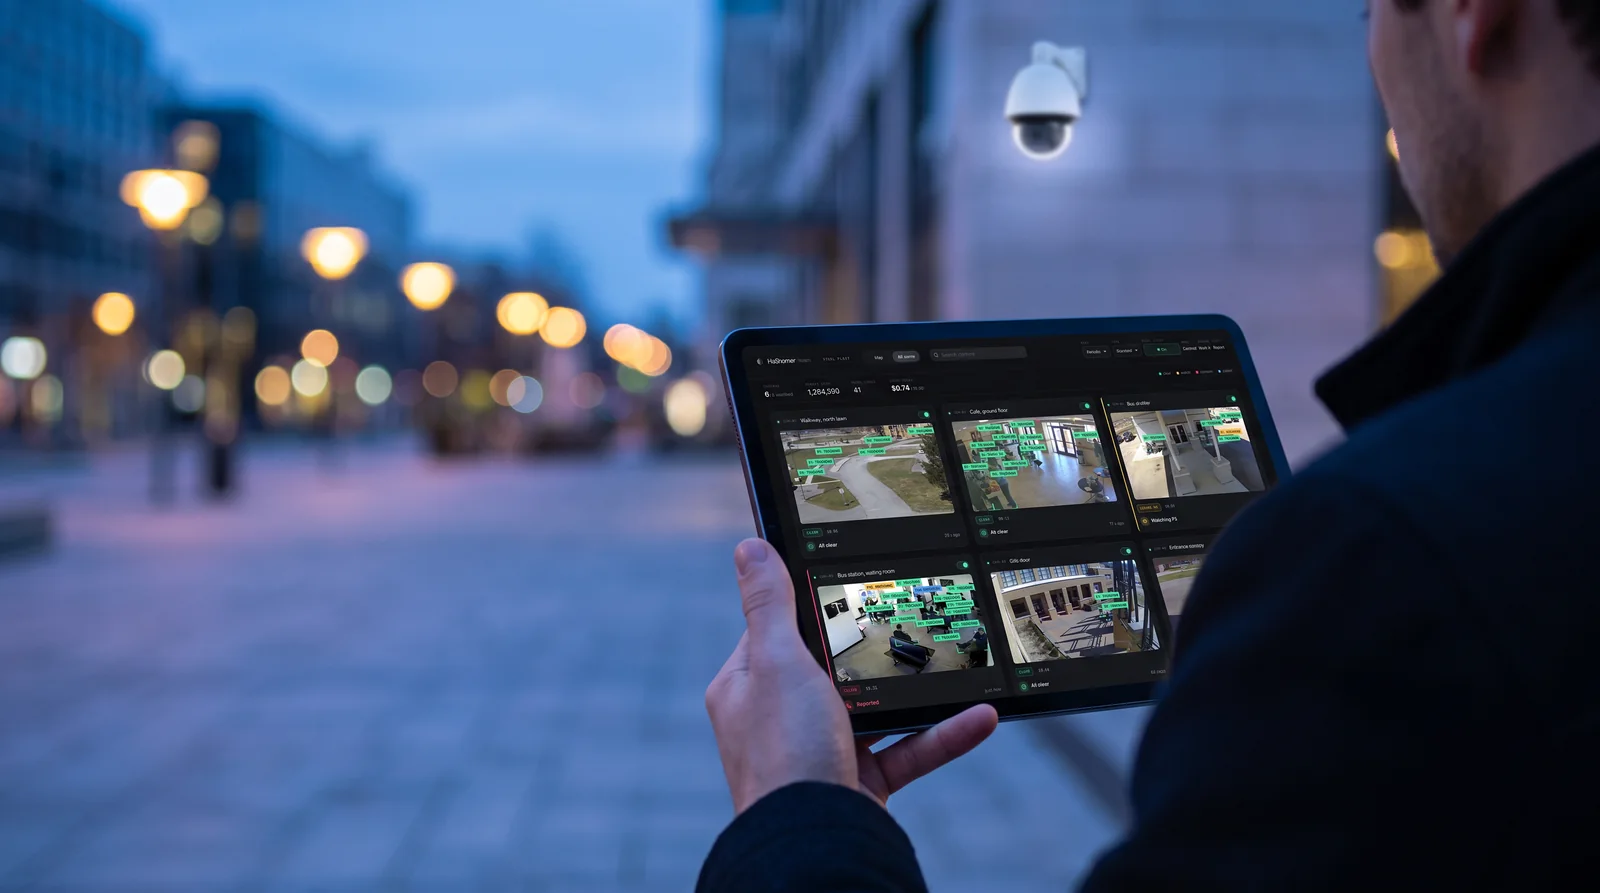
PreviewThis is the screen Vigil reports to. Each camera sits on the wall with a single line under it — all clear, watching someone, or reported — so a wall of feeds is read at a glance instead of watched. Open a camera and it shows who it is looking at, and why.
Green, yellow, red
One word per camera. Green is the answer almost every street gives almost all of the time; yellow means it is watching one person; red means it has reported, and it says what it saw.
Open a camera
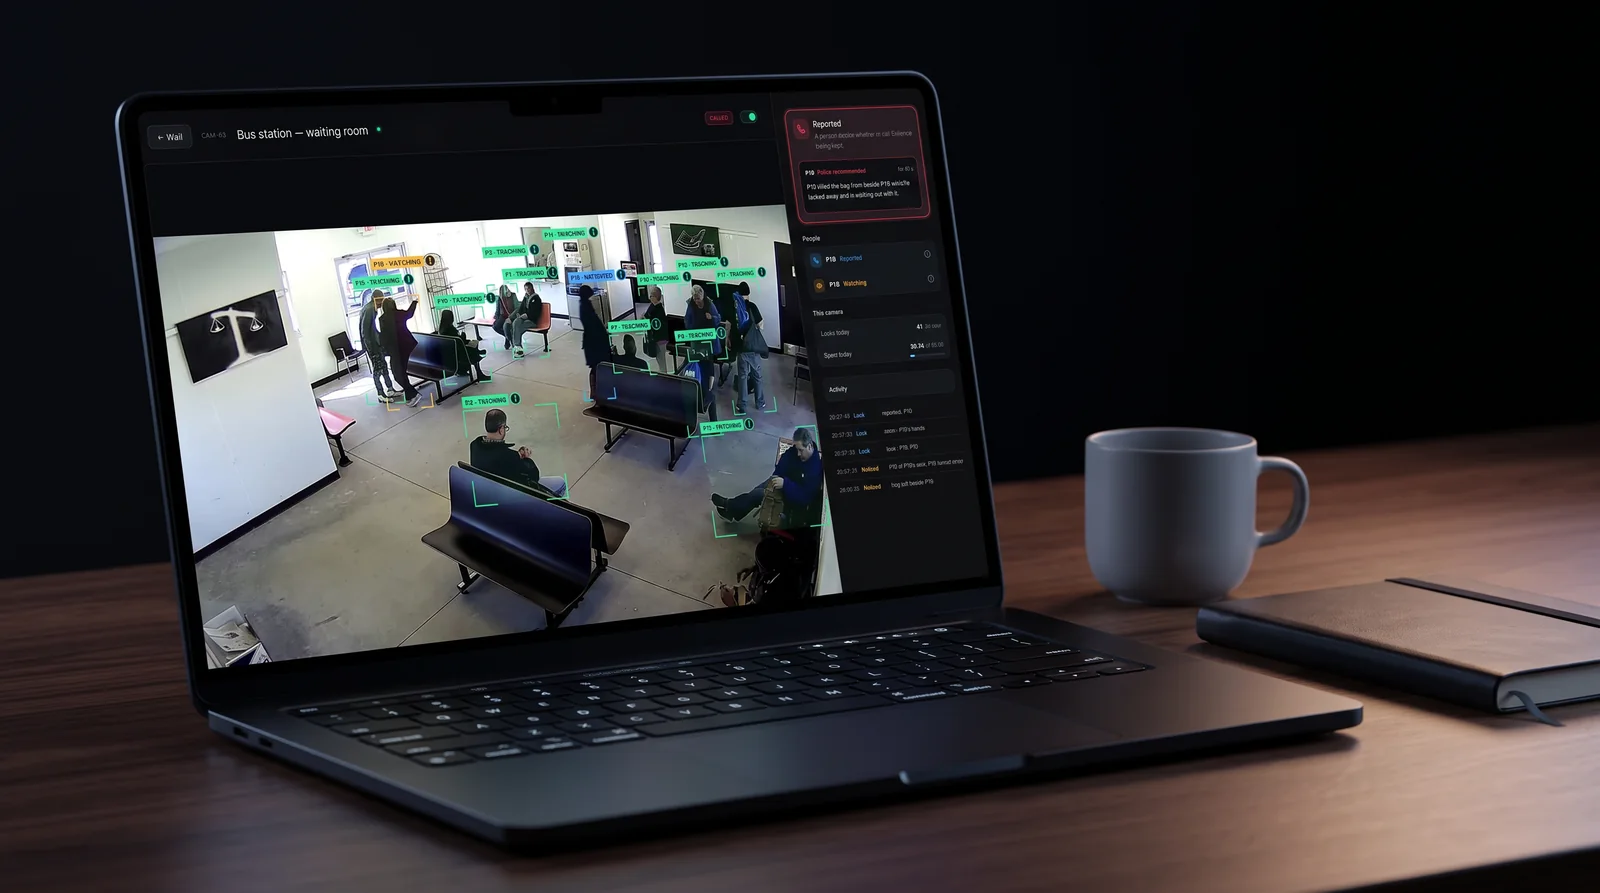
The picture fills the screen and every person keeps a number. The panel beside it says what the AI is doing there in one card, and the button on any box says why that person is the colour they are.
A person decides
Vigil recommends; it never calls anyone. A report stays on screen, framed in red, with the clip that proves it, until somebody acts on it.
A walkthrough of the live wall, with your questions answered.
Illustrations, made with AI from screens of the Vigil wall running on MEVA test footage (Kitware & IARPA, CC BY 4.0, acted by paid actors). The verdicts shown are examples.
Platform
01Motion detection fires on a bin bag in the wind. Vigil answers the question a person would ask: what is happening, how bad is it, and can you show me.
A running prototype today, with a local console, live camera input and a stored event history. It reads pose rather than pixels, which is what lets it tell a person who sat down from a person who went down.
Vigil · from frame to record
SchematicPrototype pipeline. Steps 02 and 03 run on the box and cost nothing; on an empty street the chain never reaches step 04. Nothing in it identifies a person, and nothing in it dials — see sections 03 and 05.
How it decides
02Asking one model to judge a scene and identify what is in a hand gets you a worse answer to both. So the work is split, and the harder half gets its own model and its own question.
The first watches the place and decides what should happen. The second is shown a close crop of a hand and asked one thing: what is that. It has no idea what else is in the frame, and it is better for not knowing — context is what makes a model reach for a story, and the story is the first model’s job.
Model 01Judgement
Sees the whole frame, the people in it, the recording behind it, and the object report. Decides what to do.
Model 02Perception
Sees one hand, at the camera’s full resolution. Says what is held, and says plainly when it cannot tell.
What it will not use
Rules in the briefNot what somebody looks like
Clothing, a hood, a covered face, a bag, skin colour, apparent age or sex. None of it says what a person is doing.
Not what they are wearing
Or not wearing. A report may end up with the police; a description of somebody’s body in their own home belongs nowhere in it.
Not how they seem to feel
Nobody can see a state of mind in a still. People look tense because they are late, cold, ill, or on the phone.
Not where they are, against them
The place decides what an action means: standing still is ordinary in a pedestrian street and deadly in a highway lane. It never decides who a person is. Somebody in a car park at 3am is somebody in a car park.
Not what they might do
Intent is not visible. The action is. One is reportable and the other is a guess wearing a uniform.
But: your own rules
If you write down what normal looks like at your site, a departure from it is an observation — phrased against your rule, and never carried to another site.
The test the model is given, in its own words: if your recommendation would change when you imagine the same actions performed by somebody who looks different, your recommendation is wrong — redo it on the actions alone.
Vigil · see it
Two ways inLive demo
This runs the reasoning Vigil runs: find the body, decide what posture it is in, then watch whether it stops moving. Stand back so your whole body is in the frame, then work down the checklist.
Your camera opens inside this page. The video never leaves your device, nothing is recorded, nothing is uploaded, and no attempt is made to work out who you are.
Your browser will ask permission first. Stop the demo at any time and the camera is released immediately.
The last one is the point: lying down is not the alarm. Lying down and staying still is.
Not the Vigil model. Vigil runs YOLOv8-pose on local hardware; nothing of that kind runs in a browser tab, so this demo estimates pose with MediaPipe instead. The classification above it — posture, then stillness over time — is the same reasoning. A pose model is fetched from a CDN on first press, so the demo needs a connection.
What runs when
03A camera watching an empty street should cost nothing. Most cameras watch an empty street almost all of the time.
So the work is arranged as a series of gates, each one cheaper than the next and each one able to do only one thing: ask for a closer look. A stage never concludes anything on behalf of the stage above it. That rule is what makes a false alarm at the bottom harmless — the answer to a leaf in the wind is a second glance that finds nothing, and a second glance costs a fraction of a penny of electricity.
Vigil · what a report may say
DisciplineA report quotes its evidence. It never improves on it.
The close look at a hand returns what it saw and how sure it was, including “I cannot tell”. The reasoning model may act on that and may disagree with it from a wider view — but it may not restate it as something firmer than it was, and it may not borrow a finding about one person and attach it to another. Uncertainty changes the answer rather than being rounded away: an object nobody could identify is a reason for someone to look at the clip, not a reason to send anyone running.
That is enforced twice. It is written into the instructions the model works from, and it is checked mechanically afterwards — every recommendation is compared against the evidence behind it, and one that claims more than the evidence supports is marked as such before a human ever reads it.
And nothing in the system dials anybody. Vigil recommends; a person decides and makes the call. That is deliberate, and it is not a stage we intend to remove.
In practice
04What the stages above look like when something actually happens: who notices, what it costs, and the moment a person takes over.
Pick a night and let it play, or drag along the bar. Every step names the stage that acted. The money only moves when the gate opens, and the last step is always a person.
Illustrative. These show how Vigil is built to respond, stage by stage, using the prototype's own pipeline and its cost per paid look. They are not recordings of real incidents, and the places and times are invented.
Limits
05Vigil does not identify anybody. No face recognition, no biometric matching, no watchlist. It classifies situations, not people.
This is a design decision, not a missing feature, and it is the one we get asked to reverse most often. Two reasons hold it in place.
Nothing on this site covers that. Try one of the suggestions, or press Esc and read on.
Try